[BUG] Multi-model response feature fails to honor per-model parameter overrides
Steps to Reproduce:
Enable multi-model response as per the feature here: https://typingmind.canny.io/feature-requests/p/multi-model-responses-at-the-same-time.
Add two models to run in parallel (e.g., Claude 3.7 Sonnet and Gemini 2.5).
Set individual parameters for each model using the "Override Global Model Parameters" option:
Set Claude 3.7 temperature to
default(which should be 1 for extended thinking)Set Gemini temperature to
0.2
- Run a prompt with both models.
Expected Behavior:
Each model should use the specific parameters set in its individual override configuration. Claude should run with temperature 1 (default for thinking), and Gemini should run with temperature 0.2. Token limits and other parameters should also be respected per model.
Actual Behavior:
The system appears to apply the first model's parameter settings globally to all models in the multi-model response. As a result:
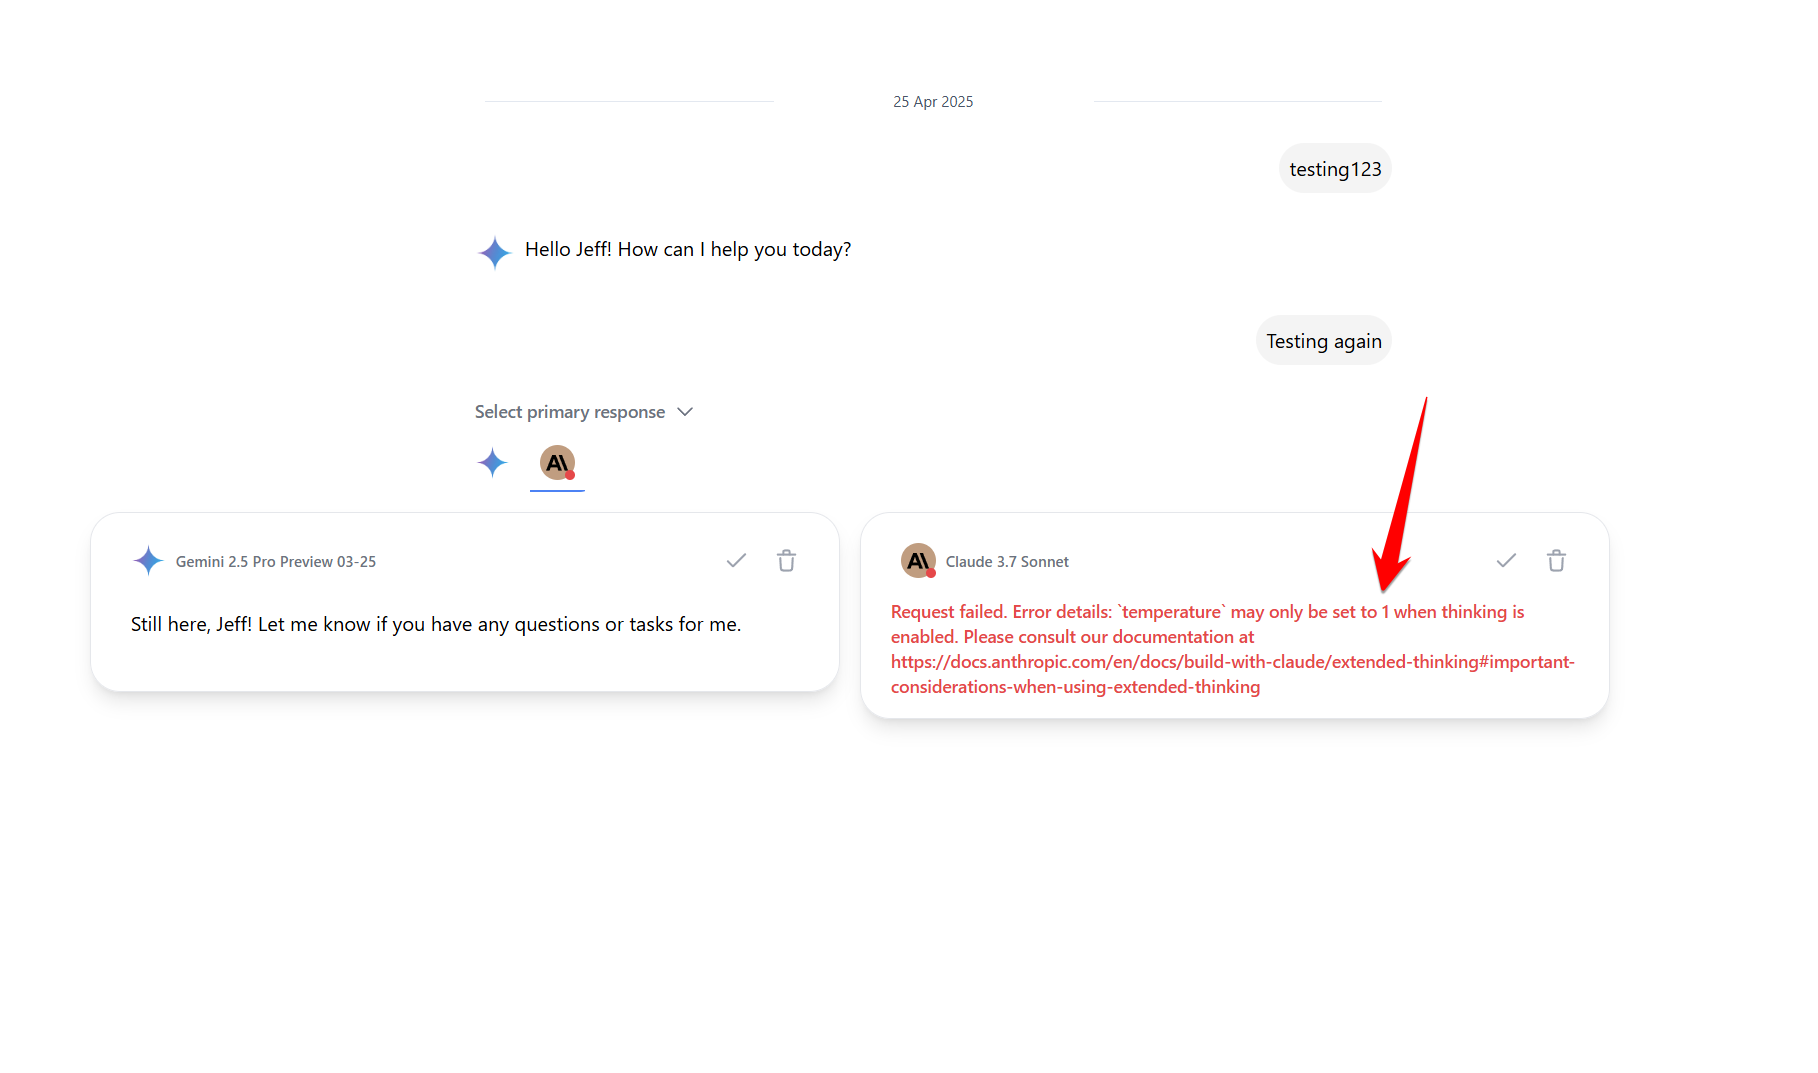
Claude 3.7 fails with the error: "temperature may only be set to 1 when thinking is enabled."
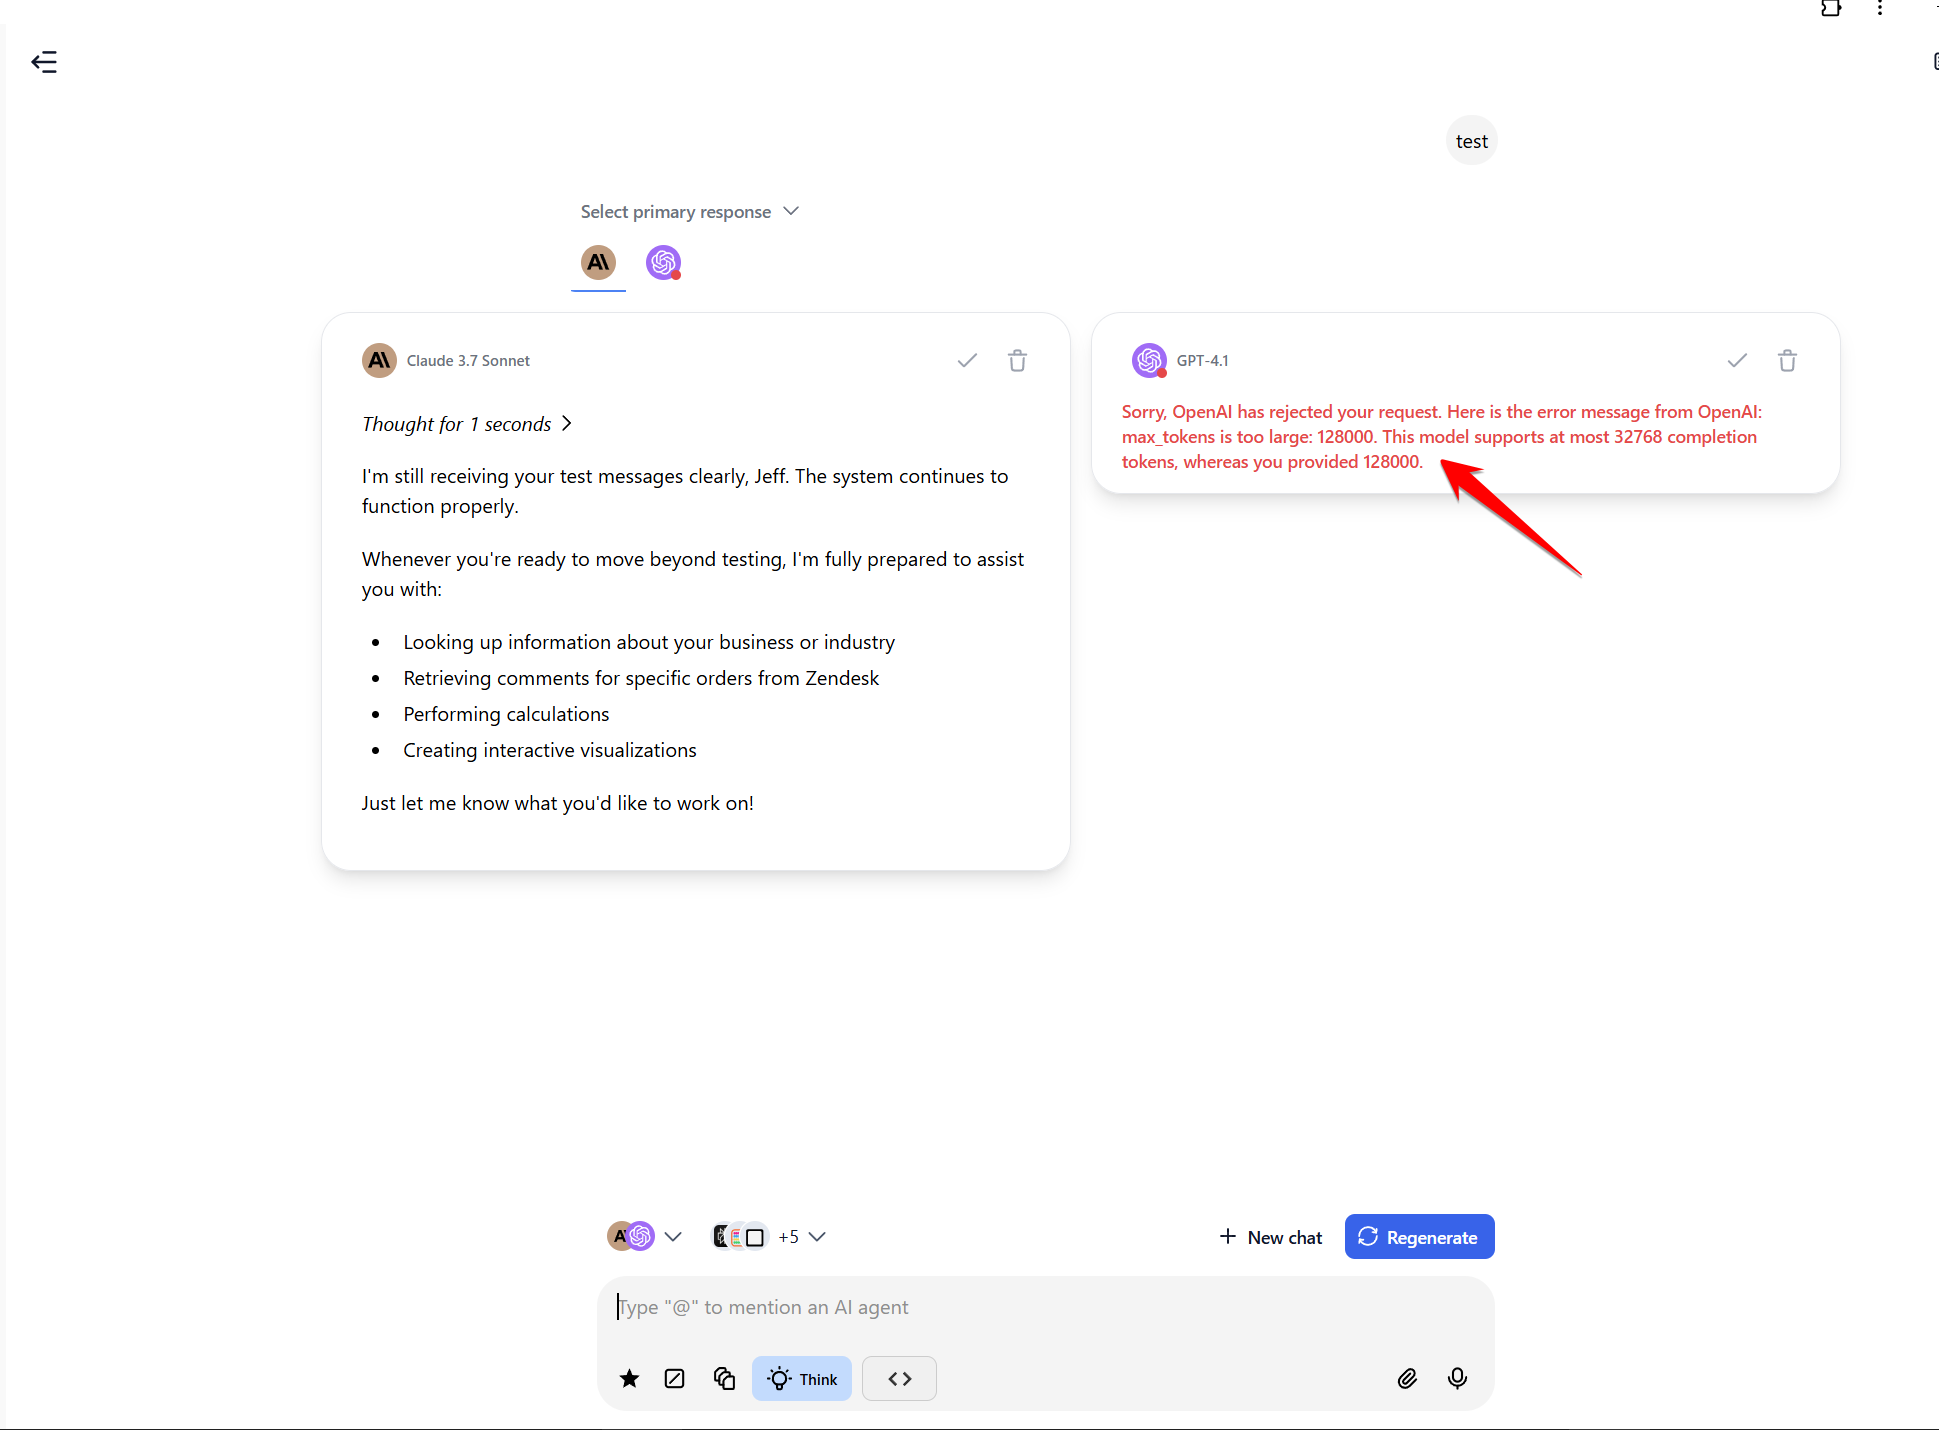
GPT-4.1 fails with the error: "max tokens is too large: 128000. This model supports at most 32768 completion tokens."
Gemini outputs using incorrect temperature settings, making comparisons inconsistent and invalid.
Screenshots:
GPT-4.1 token limit error shown in multi-model response
Claude 3.7 temperature error in multi-model usage
Log in to comment and vote
Comments3
Dec 8, 2025
PinnedThis should be fixed now!
Lavender Goat
Apr 30, 2025
I'm getting the same issue as well, is this is a glitch and will it be fixed? Tony Dinh
Coral Deer
Apr 25, 2025
Tony Dinh